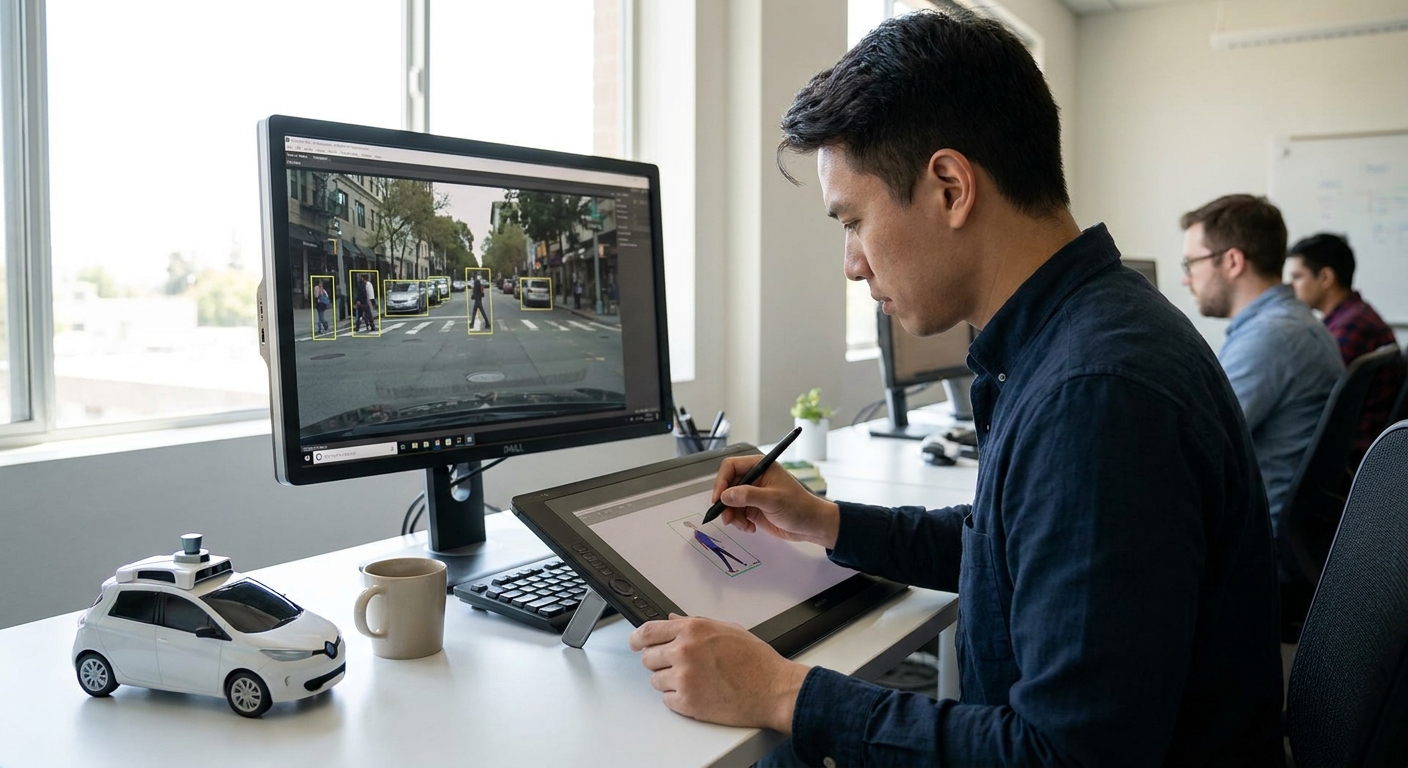
Autonomous vehicle perception models fail in production for one reason more than any other: the training data never covered the scenario the car actually hit. This guide covers what data annotation for autonomous vehicles requires in 2026 — sensor coverage, edge-case sourcing, throughput, and quality control — and which annotation approach fits which perception workload.
- Data annotation for autonomous vehicles needs camera, LiDAR, and radar fusion coverage — Rapidata's computer vision annotation handles this. Buy.
- RLHF preference data collection fixes planner and behavior-model edge cases that static bounding boxes miss. Buy.
- Simulation-to-real generative video evaluation catches synthetic training data that looks right but drives wrong. Consider.
- In-cabin voice and driver-assistant labeling needs LLM fine-tuning data, not object-detection pipelines. Consider.
- Chatbot-style RLHF formats don't map to real-time perception stacks in 2026 — skip for this use case.
Why this matters
Perception stacks in 2026 run on multi-modal sensor fusion — camera, LiDAR, radar — and every added modality multiplies the labeling burden. A single 10-second LiDAR clip can carry thousands of individual point-cloud annotations once you count every pedestrian, cyclist, and parked car in frame.
Data annotation for computer vision models built for this exact workload runs on a crowd-sourced annotator base spanning 192 countries and more than 30 million annotators, processing at 5,000+ annotations per minute. That throughput is the difference between a labeled dataset ready in days instead of months and a perception team stuck waiting on an in-house labeling queue.
The stakes are higher than in most computer vision work. A mislabeled pedestrian in a shopping dataset costs a bad recommendation. A mislabeled pedestrian in an AV perception dataset costs a false negative at 35 mph.
Who this is for
This guide is for perception engineers, ML leads, and data ops teams at AV companies, ADAS suppliers, and robotaxi operators who need labeled sensor data, edge-case scenario datasets, or RLHF preference data to train or evaluate detection, tracking, and planning models. If you're choosing between building an in-house labeling team and using an API-based annotation platform, the criteria below apply directly.
What to look for in data annotation for autonomous vehicles
Sensor modality coverage
AV perception models fuse camera, LiDAR, and radar streams, so an annotation pipeline that only handles 2D image bounding boxes leaves a gap. Look for annotation support across 3D point clouds and multi-camera synchronization, not just flat imagery, because a model trained on single-modality labels underperforms the moment sensor fusion enters the pipeline.
Edge-case and rare-event sourcing
Common scenarios — clear weather, straight highway, daytime — get labeled fast and get labeled everywhere. The scenarios that break perception stacks are occluded pedestrians, sun glare, unprotected left turns, and construction zones. An annotation source that only draws from a narrow annotator pool will keep handing you the same easy 90% of the distribution.
Annotation throughput and turnaround
A perception team iterating on model versions every few weeks can't wait a month for a labeled dataset. Rapidata's pipeline processes 671M+ annotations across its platform history at 5,000+ annotations per minute, which turns a multi-week labeling cycle into a same-week one.
Quality control and reward-model integrity
Human feedback used for RLHF-style preference tuning is only useful if the reward signal can't be gamed. A reward model that annotators or adversarial inputs can trick produces a planner model that learns the wrong lesson quietly, and you won't see it until deployment.
Global annotator diversity
Road conditions, driving norms, and pedestrian behavior differ by country. A labeling workforce concentrated in one region will under-represent scenarios common elsewhere — roundabout etiquette in Europe, motorbike density in Southeast Asia, snow-covered lane markings in the northern US. A 192-country annotator base captures more of that variance than a regional labeling shop can.
API and SDK integration
Perception teams ship models on tight cycles, so annotation has to plug into existing MLOps pipelines rather than sit as a manual side process. Job Definition-style API calls that return structured labels directly into your training pipeline save the engineering hours that manual CSV handoffs burn.
Top picks for AV perception data annotation
The core pick — computer vision annotation for detection and tracking. Data annotation for computer vision models covers 2D bounding boxes, instance segmentation, and 3D point-cloud labeling in one pipeline, drawing from a 30M+ annotator pool across 192 countries. This is the base layer for any object-detection or tracking model in a perception stack. Buy.
The behavior-tuning pick — RLHF preference data for planner models. How to collect RLHF preference data at scale fixes the gap that static labels can't — ranking planner decisions against human judgment on edge cases like unprotected turns or ambiguous right-of-way. Bounding boxes tell a model what's in the scene; preference data tells it what the right response looks like. Buy.
The simulation-validation pick — generative video model evaluation. Model evaluation for generative video models matters if your team generates synthetic driving scenes for training augmentation, because synthetic clips that look photorealistic can still contain physically wrong motion. Evaluating those clips against human judgment before they enter a training set catches the failure mode before it costs a model iteration. Consider.
The in-cabin pick — LLM fine-tuning data for voice assistants. Data labeling for LLM fine-tuning applies if your AV platform runs an in-cabin voice assistant or driver-monitoring dialogue system, which is a language task, not a perception task, and needs its own labeling pipeline rather than being bolted onto the vision stack. Consider.
The mismatch pick — chatbot-style RLHF preference data. RLHF preference data built for chatbot conversation ranking doesn't map cleanly onto real-time perception or planning decisions, where the output space is control actions, not text turns. If a vendor pitches this format for your perception stack, that's a sign they're repurposing a generic pipeline rather than building for AV. Skip.
What to avoid
- Single-modality-only labeling shops. A vendor that only offers 2D image bounding boxes will look cheap and fast until you need 3D point-cloud annotation for LiDAR, and by then you're managing two vendors instead of one.
- Static label sets with no preference-ranking option. Detection labels alone can't tune a planner's behavior in ambiguous scenarios — you need human preference data to close that gap, and a vendor without an RLHF-style offering leaves that work undone.
- Small, regionally concentrated annotator pools. A labeling team drawn from one country will systematically under-represent the driving conditions and pedestrian behaviors common elsewhere, and that gap shows up as false negatives in deployment, not in your validation metrics.
Get AV perception data labeled fast
API access to 30M+ annotators across 192 countries, live in days.
Verdict comparison
| Approach | Sensor coverage | Turnaround | Best for | Verdict |
|---|---|---|---|---|
| Computer vision annotation | Camera, LiDAR, 3D point cloud | Days | Object detection, tracking | Buy |
| RLHF preference data | Planner decisions, behavior ranking | Days | Edge-case behavior tuning | Buy |
| Generative video model evaluation | Synthetic scene validation | Days to weeks | Simulation data QA | Consider |
| LLM fine-tuning data labeling | In-cabin voice, dialogue | Days | Driver-assistant systems | Consider |
| Chatbot RLHF format | Text-turn ranking | N/A for perception | Conversational AI only | Skip |
FAQ
What is data annotation for autonomous vehicles?
Data annotation for autonomous vehicles is the process of labeling sensor data — camera images, LiDAR point clouds, radar returns — so perception models can learn to detect and track objects like pedestrians, vehicles, and lane markings. In 2026 most AV teams combine object-detection labeling with RLHF-style preference data for planner and behavior models.
How much does AV perception data annotation cost in 2026?
Cost depends on sensor modality, annotation complexity, and volume, with 3D point-cloud labeling costing more per clip than 2D bounding boxes because of the added spatial complexity. API-based crowd-sourced platforms typically price per annotation or per job rather than per headcount, which scales cost with actual labeling volume.
What's the difference between 2D bounding boxes and 3D point cloud labeling?
2D bounding boxes mark objects within a flat camera image, while 3D point-cloud labeling annotates objects within LiDAR's spatial data, capturing depth, orientation, and distance. Perception stacks that fuse camera and LiDAR need both formats aligned to the same objects across frames.
Is RLHF used in autonomous vehicle planning models?
Yes, RLHF-style preference data is increasingly used to tune planner and behavior models on ambiguous scenarios like unprotected turns, where static labels can't capture the right response. Human raters compare candidate planner decisions and rank them, and that ranking becomes the training signal.
How many annotators does it take to label a LiDAR dataset?
It depends on dataset size and clip length, but large-scale platforms draw from annotator pools in the tens of millions to keep turnaround fast. A crowd-sourced base spanning 192 countries and 30M+ annotators can label a multi-thousand-clip dataset in days rather than the weeks an in-house team would need.
What's the fastest way to label edge-case driving scenarios in 2026?
The fastest approach combines a large, geographically diverse annotator pool with an API pipeline that returns structured labels directly into training infrastructure. Platforms processing 5,000+ annotations per minute cut labeling cycles from months to days for rare-event datasets.
Can crowd-sourced annotators handle LiDAR point clouds accurately?
Yes, with proper task design and quality control, crowd-sourced annotators can label 3D point clouds at accuracy levels comparable to in-house teams, especially when annotation instructions include reference frames and quality-check redundancy. Reward-model integrity matters here — labels used for preference tuning need to resist gaming by adversarial or low-effort responses.
How long does AV perception dataset labeling take with an API?
API-based annotation platforms typically deliver labeled datasets in days rather than the weeks or months an in-house labeling team requires, because the workload distributes across a large annotator pool instead of a fixed headcount. Turnaround scales with dataset size but stays measured in days for most perception workloads in 2026.
One last thing
The annotation format most AV teams skip until it's too late is RLHF preference data for planner behavior — bounding boxes tell a model what's in front of it, but only human preference rankings tell it what the correct response to an ambiguous scene should be, and that gap is where most perception-to-planning failures actually originate.