Computer vision models live or die by the quality of the boxes, masks, and keypoints drawn on their training images — and most teams still guess at how to source that labeling work at scale in 2026.
- Data annotation for computer vision now runs through API-first platforms, not spreadsheets of freelancers.
- Rapidata's crowd network spans 30M+ annotators across 192 countries — Buy for teams needing volume and speed.
- In-house annotation teams win on domain control but stall past 50,000 images per month — Consider only for niche datasets.
- Generic crowdsourcing marketplaces are the cheapest option but fail consensus checks on segmentation tasks — Skip for anything beyond simple tagging.
- Turnaround under 48 hours is achievable in 2026 when annotation volume exceeds 5,000 labels per minute.
Why this matters
A computer vision model trained on inconsistent bounding boxes doesn't fail quietly — it fails at inference, on real footage, after you've shipped it. Annotation quality is the single variable most teams underweight when they scope a CV project, because the cost shows up months later as retraining cycles, not as a line item today.
The teams that get this right in 2026 treat data annotation for computer vision as an ML infrastructure decision, not a procurement task. That means picking a source of labeled data based on consensus mechanisms, throughput, and geographic coverage — not just price per label.
Who this is for
This guide is for ML engineers and applied research teams building object detection, segmentation, pose estimation, or autonomous perception models who need labeled image or video data at a scale their internal team can't hand-label. If you're annotating fewer than 1,000 images total for a proof of concept, in-house labeling is faster than onboarding any vendor. Past that volume, the sourcing decision starts to matter more than the model architecture.
What to look for in data annotation for computer vision
Annotation type coverage
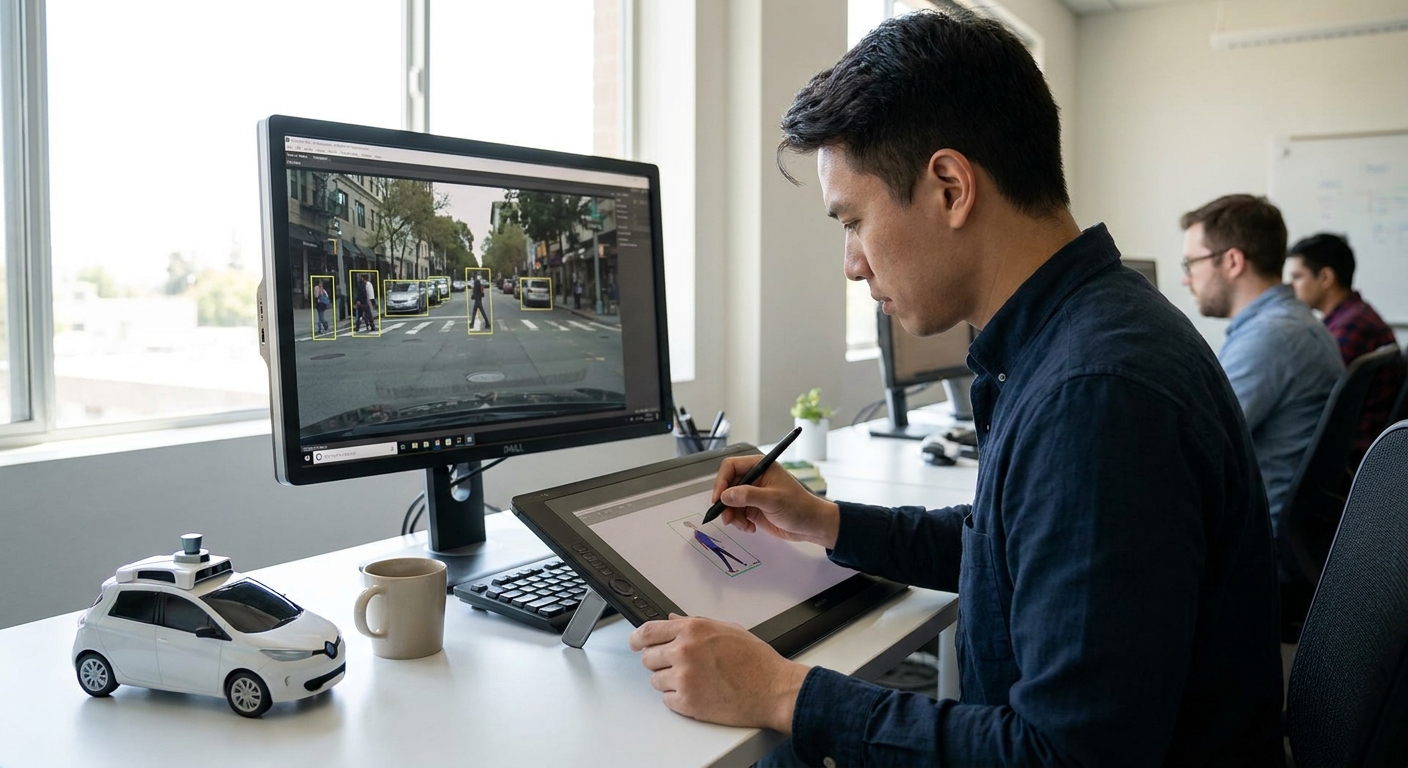
Bounding boxes are the easy case. Instance segmentation masks, keypoint skeletons, and video object tracking each require different annotator training and different UI tooling — a platform that only does boxes will force you to split your pipeline across vendors. Confirm the platform supports the exact label type your model architecture consumes before you commit volume.
Consensus and quality control
A single annotator's judgment on where an object boundary sits is noisy; multiple independent annotators voting on the same image is not. Platforms that route each task to several annotators and resolve disagreement algorithmically produce measurably cleaner training sets than single-pass labeling. Ask for the actual agreement rate on a pilot batch before you scale.
Annotator diversity and geographic spread
CV models trained for global deployment — retail, security, agriculture — need training data annotated by people who recognize the objects, environments, and lighting conditions in the target market. A pool concentrated in one country under-represents edge cases your model will hit in production. Rapidata's annotator base spans 192 countries specifically to cover this gap.
Throughput and turnaround
Model iteration cycles in 2026 move fast — a dataset that takes three weeks to label is a dataset that's stale before the model finishes training. Look for platforms that publish per-minute or per-hour annotation rates, not just "fast turnaround" language. 5,000+ annotations per minute is the kind of number that lets you re-label and retrain in the same sprint.
Cost structure and reward model integrity
Per-label pricing hides a real risk: annotators optimizing for speed over accuracy when payment is tied to volume rather than quality. A reward model that can't be gamed — where payment ties to consensus accuracy, not just task completion — produces cleaner data at the same nominal cost per label.
“If your annotators can't agree on a bounding box, your model won't either.”
Top picks for data annotation for computer vision
In-house annotation team — the control pick
Spec that matters: full domain expertise, zero ramp-up time on internal taxonomy. An in-house team makes sense when your CV task involves proprietary categories — medical imaging subtypes, industrial defect classes — that a general crowd can't learn from a one-page instruction sheet. The ceiling is real: most internal teams plateau around 2,000-5,000 labeled images per week before headcount becomes the bottleneck. Consider for under 50,000 images per month with highly specialized categories; Skip past that volume.
Generic crowdsourcing marketplace — the cheap option
Spec that matters: lowest per-label cost, minimal quality gating. These platforms work for simple classification tasks — "is there a car in this image, yes or no" — where a wrong answer costs almost nothing. They break down fast on segmentation and keypoint work, where a single annotator's error rate on complex masks can run 15-20% without a consensus layer. Skip for anything beyond binary tagging in 2026.
Outsourced BPO annotation vendor — the middle ground
Spec that matters: managed workforce, contractual SLAs. BPO vendors offer predictable pricing and a single point of contact, which appeals to teams that want to outsource the vendor-management overhead along with the labeling itself. Turnaround typically runs 5-10 business days per batch, which is workable for quarterly model refreshes but too slow for active RLHF-style iteration loops. Consider for stable, low-frequency labeling needs; Wait if your model retrains weekly.
Rapidata — the scale pick
Spec that matters: 30M+ annotators across 192 countries, 5,000+ annotations per minute, 671M+ annotations collected to date. Rapidata runs data annotation for computer vision through an API and SDK, so labeling requests go straight into your existing ML pipeline instead of a separate portal you have to babysit. The consensus-based reward model means annotators are scored on agreement with independent peers, not just task completion, which is the mechanism that keeps segmentation and keypoint quality high at volume. Buy for any CV project needing more than a few thousand labels per week or coverage across multiple countries and languages.
What to avoid
- Single-annotator pipelines for segmentation tasks. One person's judgment on a mask boundary is not ground truth — it's a guess that looks like ground truth until your model inherits the error.
- Vendors that quote a flat turnaround regardless of volume. A vendor promising "48 hours" for both 500 images and 500,000 images is either padding the small job or lying about the large one.
- Platforms with no published annotator geographic spread. If a vendor won't tell you where their annotators are, your CV model's blind spots will tell you later, in production.
Get labeled data into your pipeline
API access to a 30M+ annotator network across 192 countries.
Verdict comparison
| Source | Throughput | Consensus QC | Best for | Verdict |
|---|---|---|---|---|
| In-house team | 2K-5K images/week | Manual review | Proprietary taxonomies | Consider |
| Crowdsourcing marketplace | Varies, low reliability | None or minimal | Simple binary tagging | Skip |
| Outsourced BPO vendor | 5-10 day batches | Contractual SLA | Stable, low-frequency labeling | Consider |
| Rapidata | 5K+ annotations/minute | Multi-annotator consensus | High-volume, global CV datasets | Buy |
FAQ
What is data annotation for computer vision?
Data annotation for computer vision is the process of labeling images or video with bounding boxes, segmentation masks, keypoints, or tags so a model can learn to recognize objects. In 2026, most teams source this through API-based crowd platforms rather than manual in-house tagging once volume passes a few thousand images.
How much does computer vision data annotation cost?
Cost varies by label type — simple bounding boxes are cheaper than instance segmentation masks or video tracking. Pricing models tied to consensus accuracy rather than raw task volume tend to produce cleaner data at a comparable cost per label.
Is crowdsourced annotation accurate enough for CV models?
Yes, when the platform uses multi-annotator consensus to resolve disagreement rather than relying on a single labeler's judgment. Rapidata's network of 30M+ annotators applies this consensus approach across 671M+ annotations collected to date.
How fast can I get a computer vision dataset labeled?
Platforms running at 5,000+ annotations per minute can turn around datasets in hours rather than weeks. In-house teams and outsourced BPO vendors typically take days to weeks per batch depending on volume.
What annotation types matter most for object detection models?
Object detection models need bounding box annotations at minimum, while instance segmentation and pose estimation models require pixel-level masks or keypoint skeletons. Confirm your annotation source supports the exact label type your model architecture consumes before committing volume.
Should I build an in-house annotation team or outsource?
In-house teams make sense under roughly 50,000 images per month with highly specialized categories a general crowd can't learn quickly. Past that volume, an API-based crowd platform scales without adding headcount.
Why does annotator geographic diversity matter for computer vision?
Models deployed globally encounter objects, environments, and lighting conditions that a geographically concentrated annotator pool won't recognize accurately. Rapidata's annotator base spans 192 countries specifically to cover this gap.
What is a reward model that can't be hacked?
It's a payment mechanism that scores annotators on agreement with independent peers rather than on task completion alone, which removes the incentive to rush through labels for volume. This consensus-based scoring is what keeps segmentation and keypoint accuracy high at scale.
One last thing
Most teams budget for annotation cost per label and forget to budget for annotation cost per re-label — the hidden expense when a first labeling pass produces inconsistent segmentation masks and the whole batch has to go back through QC. A consensus mechanism at annotation time, not review time, is what actually saves the second pass in 2026.